iTAG and IEEE LOM metadata extraction
Automatic pedagogical metadata for slide decks and PDFs, so tutoring systems can find them.
Intelligent tutoring systems can only recommend a learning object if they know what it is: its difficulty, interactivity, intended audience, reading time and language, not just its title and author. The IEEE Learning Object Metadata (LOM) standard defines such fields, but filling them in by hand does not scale, so most repositories hold bibliographic metadata and little that is pedagogical.
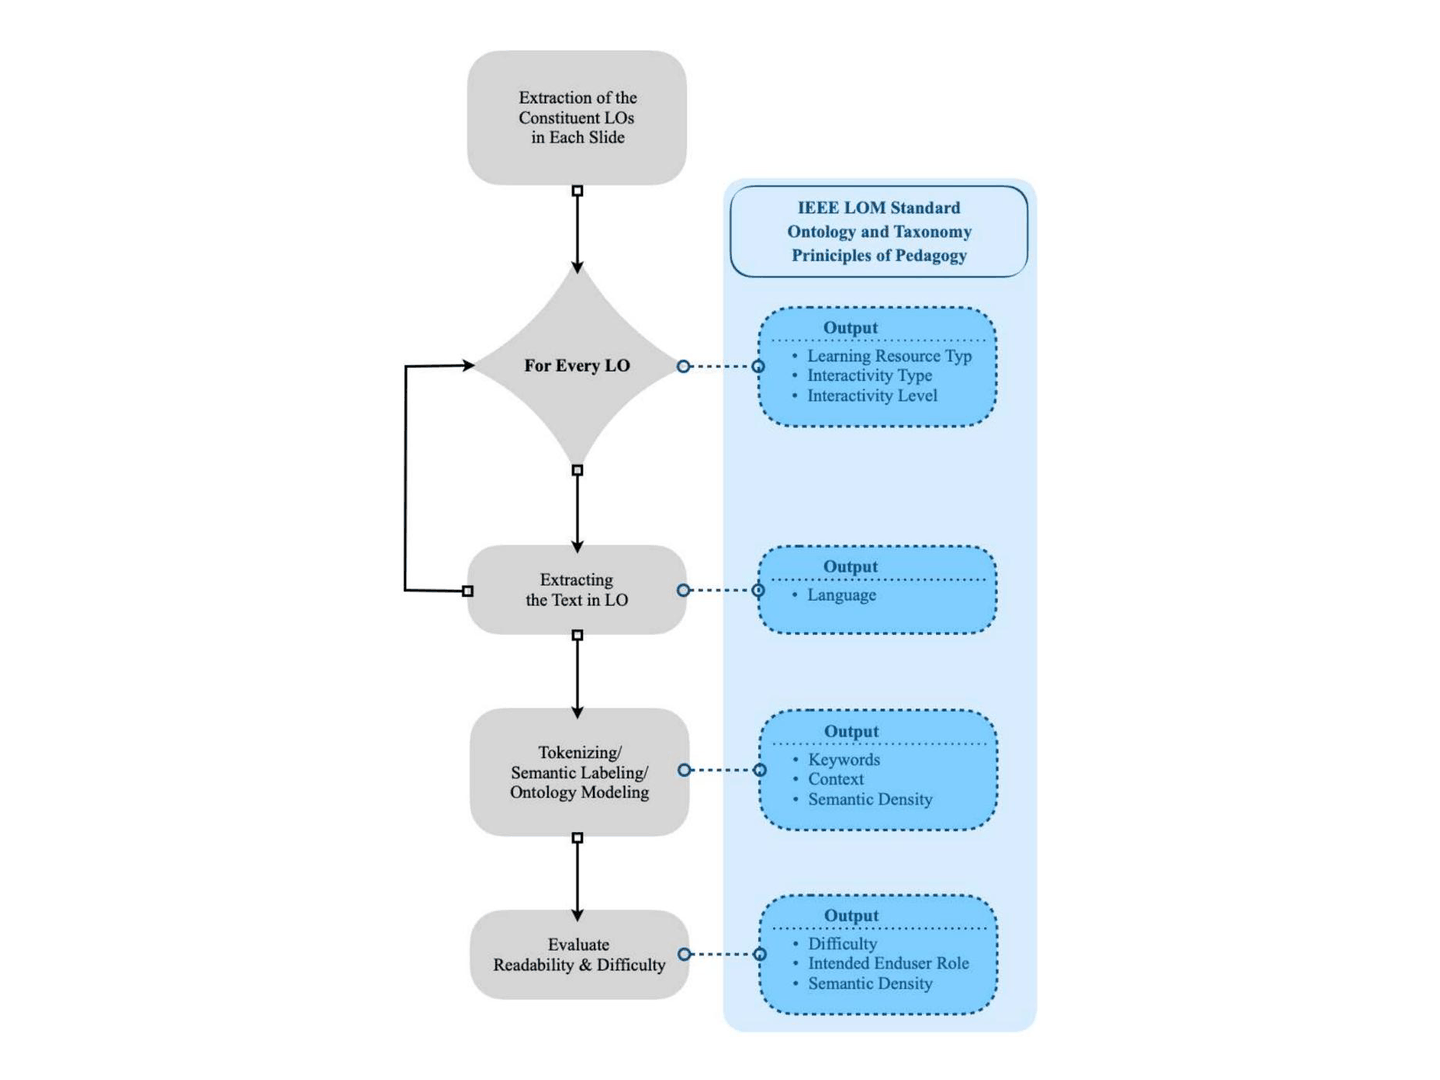
As a research assistant in the Technology Enhanced Learning Lab at the University of Tehran (2023), I built an extractor that reads PowerPoint decks and PDF documents and derives IEEE LOM fields automatically: interactivity level, semantic density, intended end-user role, context, difficulty, typical age range, typical learning time, description, language and keywords. It combines text extraction with NLP (tokenization and semantic labelling with spaCy and NLTK), readability measures and rule-based mapping onto the LOM vocabulary, and writes one JSON metadata record per document. The code is public at github.com/alikera/IEEE-LOM.
In the same lab I contributed to iTAG, an “easy, rapid, automatic intelligent tagger” for educational content led by Narges Shahhoseini and Fattaneh Taghiyareh (Shahhoseini et al., 2025). iTAG combines NLP, machine-learning techniques and domain-specific rules to annotate text-based learning objects with both general and pedagogical metadata, splitting each document into its constituent learning objects and labelling each one. In the paper’s evaluation against expert annotations, it reached 100% precision on basic fields such as interactivity type and language, and 60–70% accuracy on harder attributes such as semantic density and difficulty. The paper appeared at the 29th International Computer Conference of the Computer Society of Iran (CSICC 2025).
The motivation carries over to my current work: recommendation and feedback systems are only as good as the metadata and rubrics that describe the content they reason about.
Links: IEEE-LOM extractor (GitHub) · iTAG paper (IEEE Xplore)